A fitness-coach app on small open models, governed by CA3 on one person's own records: watch, music and what they told it. It beat the same model handed the app's summaries at every question.
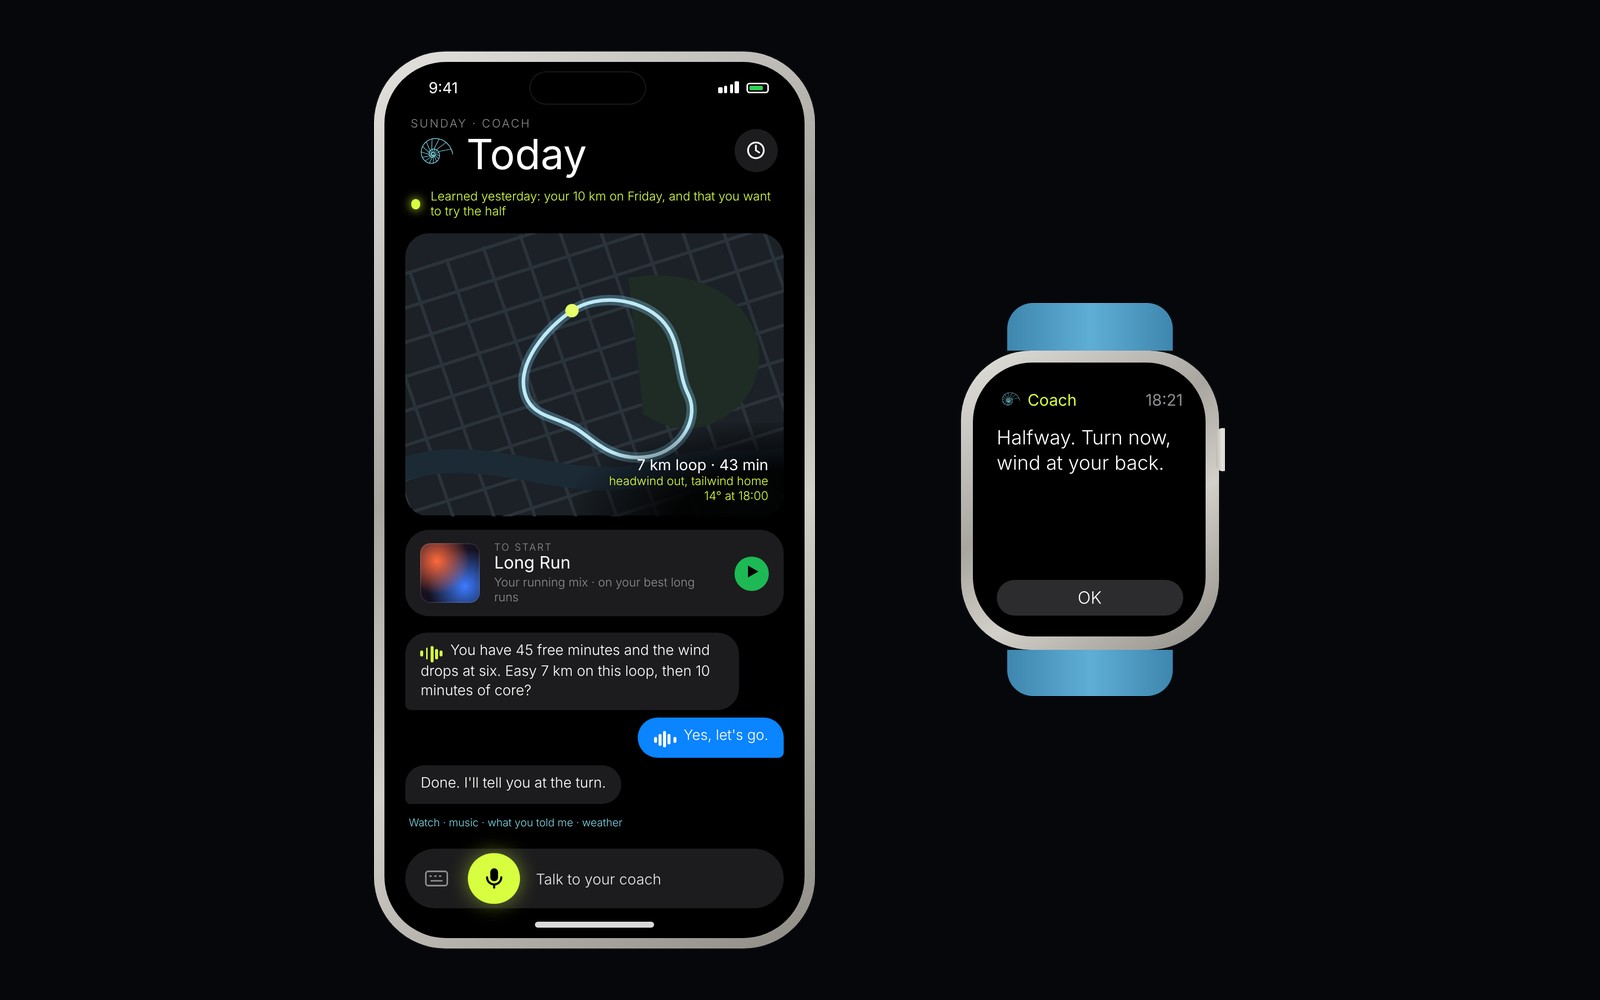
Questions that only have an answer when two records are crossed, or that need where they train. Handed the app's summaries, the same model rarely gets them.
87 pieces of advice, each judged blind by three independent AI readers against the same model given the app's summaries. The readers preferred CA3's in 69, the rival's in 16; two were ties.
Median of 56 shared questions, every model call counted.
Five days of someone else's records were planted among the owner's. CA3 left them out. On the smallest model, LittleLamb, it also kept them out and forgot a sport on request; that model was too small to give useful advice.
One person's records, six kinds of question, morning notices and one incident planted.
Compared with the same model and no CA3, given the app's summaries at every question: the last seven days, recent listening, notes and a look-up for the question. One pre-registered run, 1 November 2026.
| Measured | Asked | With CA3 | Same model, app's summaries |
|---|---|---|---|
| Advice preferred (2 ties) | 87 | 69 | 16 |
| Crossings, right | 21 | 19 | 3 |
| Places, right | 5 | 5 | 0 |
| Morning notices preferred | 25 | 24 | 1 |
| Tokens read per answer, median | 56 | 1,685 | 3,546 |
| Seconds per answer, median | 56 | 0.51 | 4.03 |
A pilot inside your own app: you choose which of your users' data it may use and what it must never say, and you measure the answers with your own users.
ContactAll twelve use casesResults from recorded, pre-registered tests. The mechanism is not shown. Model and dataset names are for identification only. Not produced or endorsed by Apple, Spotify, Multiverse Computing or Alibaba Cloud. CA3 is developed by Alberto Acedo, PhD, at Biome Makers Inc.
 CA3